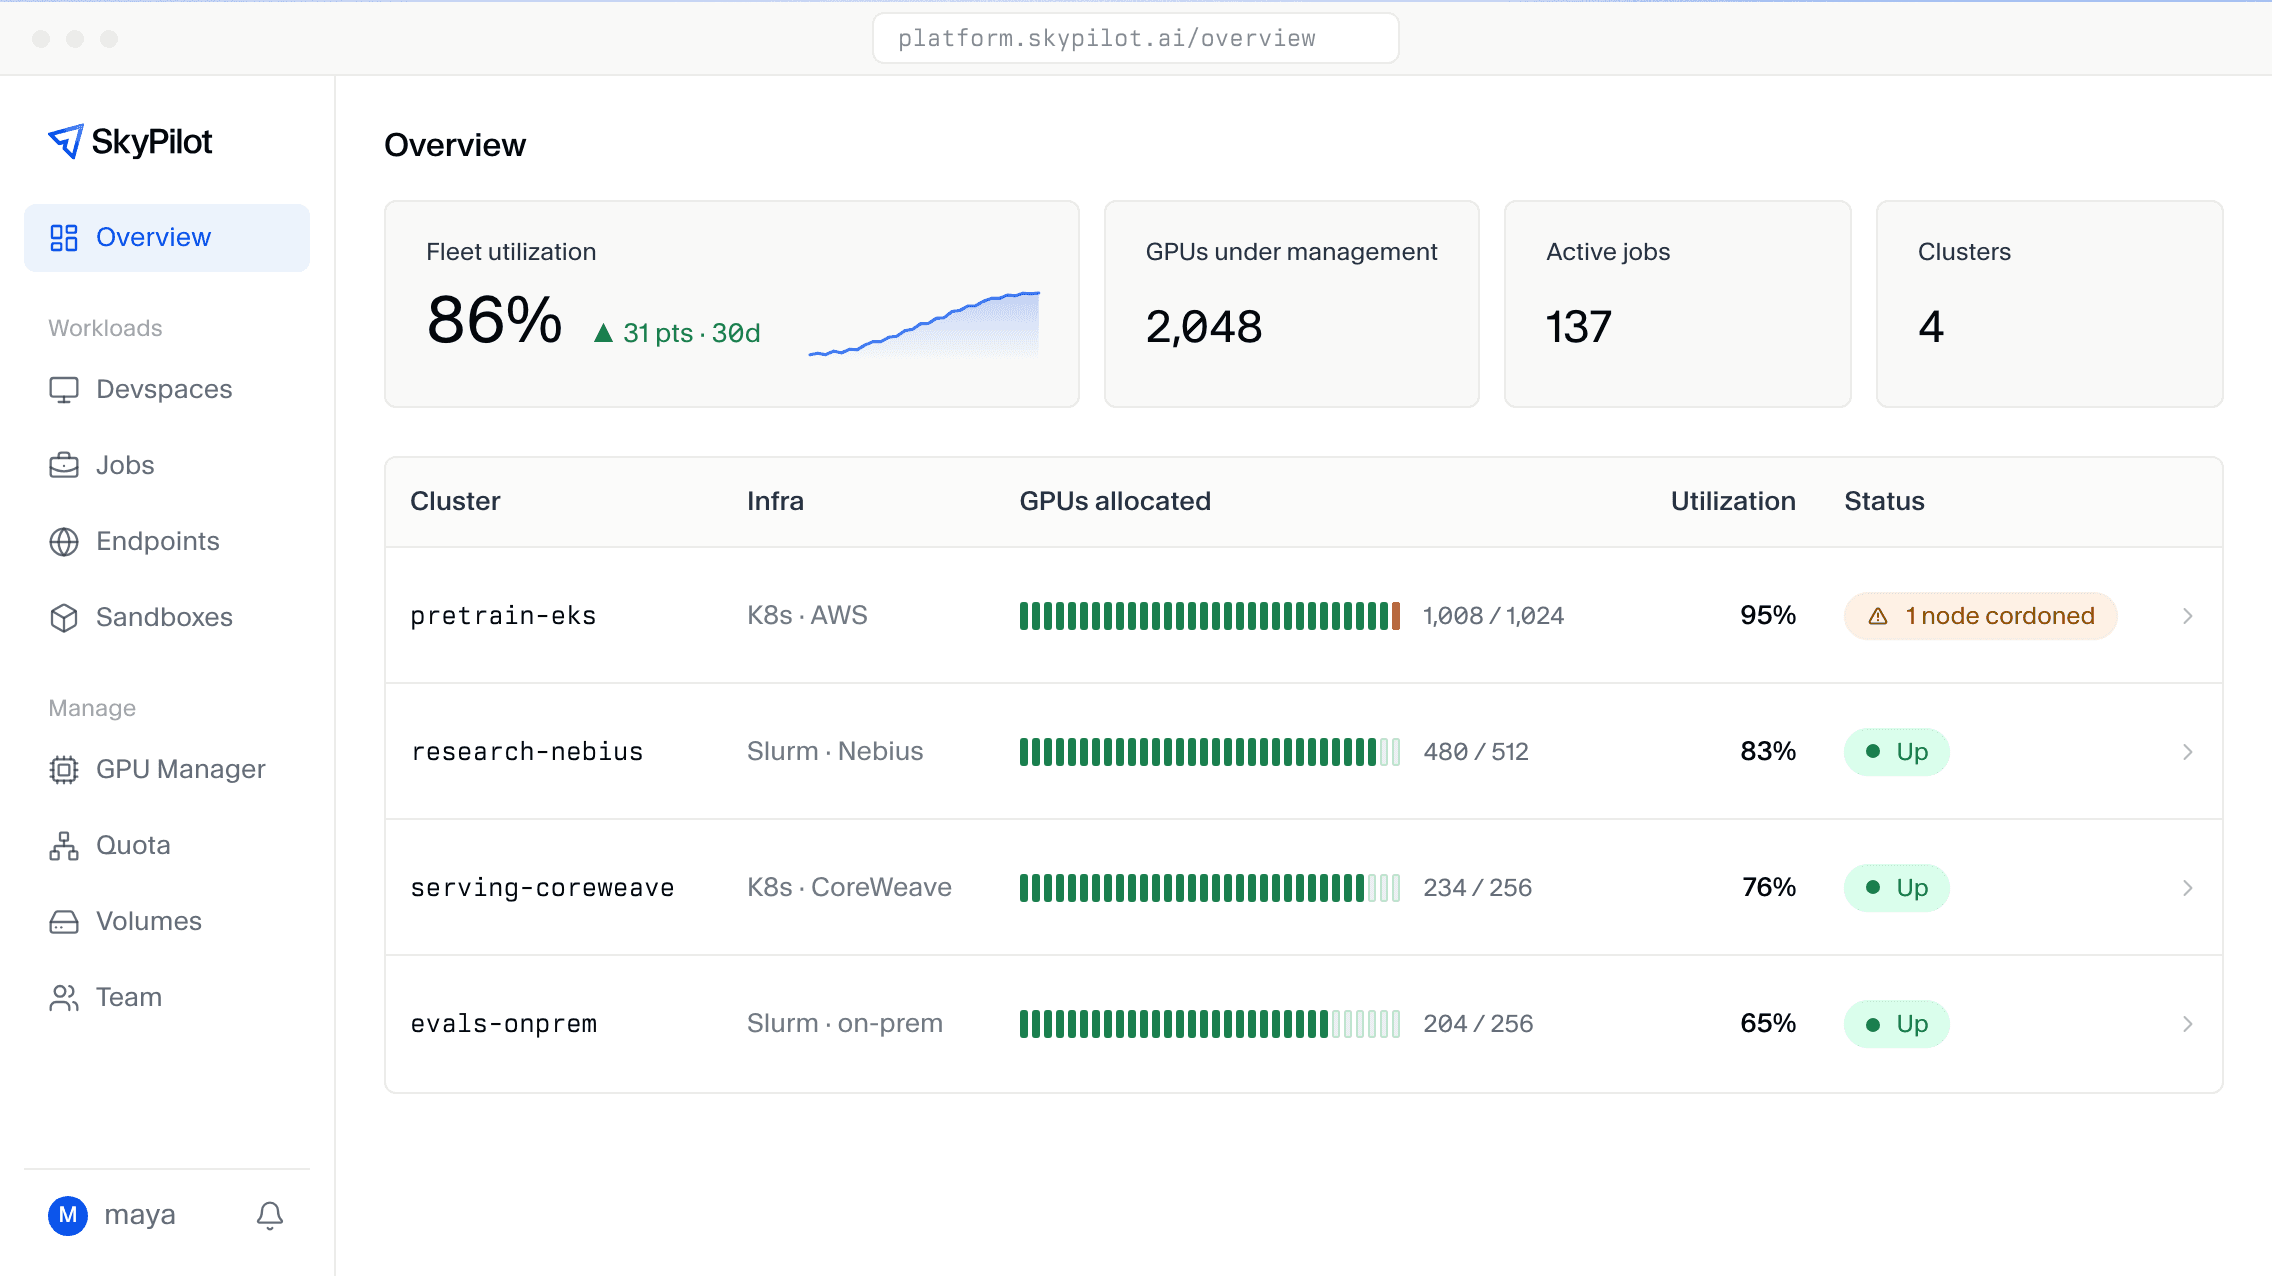
Supercharge your GPU fleet
The fully managed platform for frontier AI teams. Train and serve your AI. Maximize every GPU in your fleet.
SkyPilot is used by AI teams building the frontier


 “SkyPilot provides a flexible orchestration layer that adapts to Nubank's infrastructure and operational requirements, rather than constraining us to a rigid platform.”Abhishek Shivanna, Machine Learning Senior Manager, NubankRead testimonial“How Meta FAIR uses SkyPilot to manage AI workloads across their 100k+ GPU Slurm fleet.”Watch tech talk“We've been using SkyPilot since the early days of the company, for over 2 years. Great software + team, highly recommend :)”Erik Spock Gafni, Co-founder and CTO, TypeSafeRead testimonial“Abridge moved from SLURM to a scalable multi-cloud AI infra with SkyPilot, unlocking 10x faster development cycles.”Read story“We have been using SkyPilot at Unconventional AI to scale very quickly. So much pain removed, quick and easy ways to launch large jobs quickly.”Xavier Gonzalez, AI Researcher, Unconventional AIRead testimonial“SkyPilot gave us all of those features and more out of the box — gang scheduling, multi-node jobs, SSH access — in a unified interface across all our clouds.”Linden Li, Co-founder, Applied ComputeRead testimonial“Hundreds of researchers sharing thousands of Blackwell GPUs across hyperscalers and neoclouds was a full-time platform team's problem. With SkyPilot Platform, it runs itself — quotas, policies, and a dashboard instead of a queue of tickets.”Rahul A R, Principal Researcher, SarvamRead testimonial“H Company adopted SkyPilot as its standard AI infrastructure layer, scaling online RL to 2,000+ GPUs on Kubernetes — previously impossible on Slurm.”Read story“Moving from SLURM to SkyPilot was a strong win for us. A unified next-gen platform to manage all our clusters means we can scale GPUs exactly when we need them without lock-in.”Debajyoti Datta, Co-founder, Hippocratic AIRead testimonial
All your AI compute. One platform.
Development, training, and serving on one control plane, across every cluster and cloud you own.
Maximize every GPU.
Pool your clusters into one unified fleet and bump utilization by up to 30%.
Intelligent scheduling
- Enforce quotas with borrowing
- Guaranteed team shares; idle GPUs borrowed and returned automatically.
- Priorities and preemption
- Urgent runs preempt; preempted jobs requeue automatically.
- Topology-aware scheduling
- Multi-node jobs land on one NVL72 rack with smart binpacking and defragmentation.
- pretrain-moe-30bMediumRunning
- tokenize-webLowRunning
- mmlu-regressionLowRunning
Fleet observability
- Fleet-wide GPU map
- Live map of every device, grouped by cluster and topology.
- Automatic GPU health checks
- Faults caught, nodes cordoned, workloads recovered automatically.
- Metrics and logs
- Job logs, events, and Grafana dashboards built in.
GPU Map · 6 clusters · 2,048 GPUs
Governance
- Usage and cost tracking
- Track GPU-hours by user, team, and workload.
- Admin policies
- Enforce controls on every job at submission.
- Audit logs
- Every launch recorded: who, what, where, and when.
GPU-hours
From idea to results, faster.
SkyPilot Platform accelerates frontier AI research — from development environments to 1,000-node runs.
Devspaces
Remote GPU dev environments on your own infra, over SSH or your IDE.
- Built for agents and autoresearch
- Run coding and research agents inside every project, on your infra.
- Scale on demand
- Start with one GPU, scale up to many.
import torch
from model import GPT

net = GPT.from_pretrained(
  "ckpt/step84200")
net.to("cuda") # ready
name: sweep-lr
resources:
  accelerators: H100:1
envs:
  LR: [1e-4, 3e-4, 1e-3]
run: python train.py --lr $LR
Frontier Trainer
Training infrastructure for 1,000-node runs.
- Gang scheduling
- Native all-or-none scheduling for multi-node jobs and RL workloads.
- Dynamic hot swapping
- Faulty GPUs swapped for standby ones without restarting the run.
Sandboxes
Thousands of agent and RL sandboxes in under a second, on your infra.
- Strong isolation
- gVisor and microVM sandboxes for untrusted code.
- Snapshot and restore
- Snapshot a sandbox once, restore it anywhere.
- Running
- 0
- Ready in
- 0.0s
- Snapshots
- 0
Endpoints
Production-ready inference. One endpoint across all your clusters.
- Prefill–decode disaggregation
- Split prefill and decode for higher throughput.
- KV cache-aware routing
- Route requests to maximize cache hits.
Built for how AI teams work.
Your agents launch and manage the jobs, you get updates in Slack.
Agent-native
Let your agent launch workloads or manage your infra with the official SkyPilot Skill — get more things done faster.
Slack notifications and webhooks
Get notified on job status changes, GPU failures, and preemptions. No need to babysit your jobs or GPUs.
Enterprise governance.
High availability
Horizontally scalable control plane. No single point of failure.
SSO and RBAC
Okta/OIDC, roles and workspaces per team.
Admin policies
Compute policies for team and workload governance.
Secrets
Centrally managed credentials, never in user code.
SOC 2 Type II
Audit report available on request.
Audit logs
Who launched what, where, and when.
Fully managed by the team which builds SkyPilot.
24×7 support from the core SkyPilot team — upgrades, performance tuning, and production incidents are all handled for you.
On-premise deployments are available for select enterprise customers.
SkyPilot Platform optimizes for
large-scale fleets.
Choose the SkyPilot Platform for a fully managed experience, plus everything you need to scale.
| At scale, you need | Open sourceSkyPilot open source | PlatformSkyPilot Platform |
|---|---|---|
| Multi-cloud / K8s / Slurm orchestration | Included | Included |
| Auto-failover | Included | Included |
| Scale to millions of jobs and 100s of users | — | Built in |
| High-availability control plane | — | Built in |
| Team quotas, priorities, and queueing | — | Built in |
| GPU/NCCL failure detection and recovery | — | Automatic |
| Cost tracking and per-user GPU-hours | — | Built in |
| Fleet observability and audit logs | — | Built in |
| SSO, RBAC, admin policies | — | Built in |
| Devspaces, Sandboxes, Endpoints | — | Included |
| Support | —Community | 24×7 experts |
Proven at the frontier.
“We have been using SkyPilot at Unconventional AI to scale very quickly. So much pain removed, quick and easy ways to launch large jobs quickly.”

“SkyPilot provides a flexible orchestration layer that adapts to Nubank’s infrastructure and operational requirements, rather than constraining us to a rigid platform.”

“Previously, the ML infra team was pinged daily on issues like ‘Why is the job not being scheduled?’… With SkyPilot we rarely get pinged. It just works!”
